About
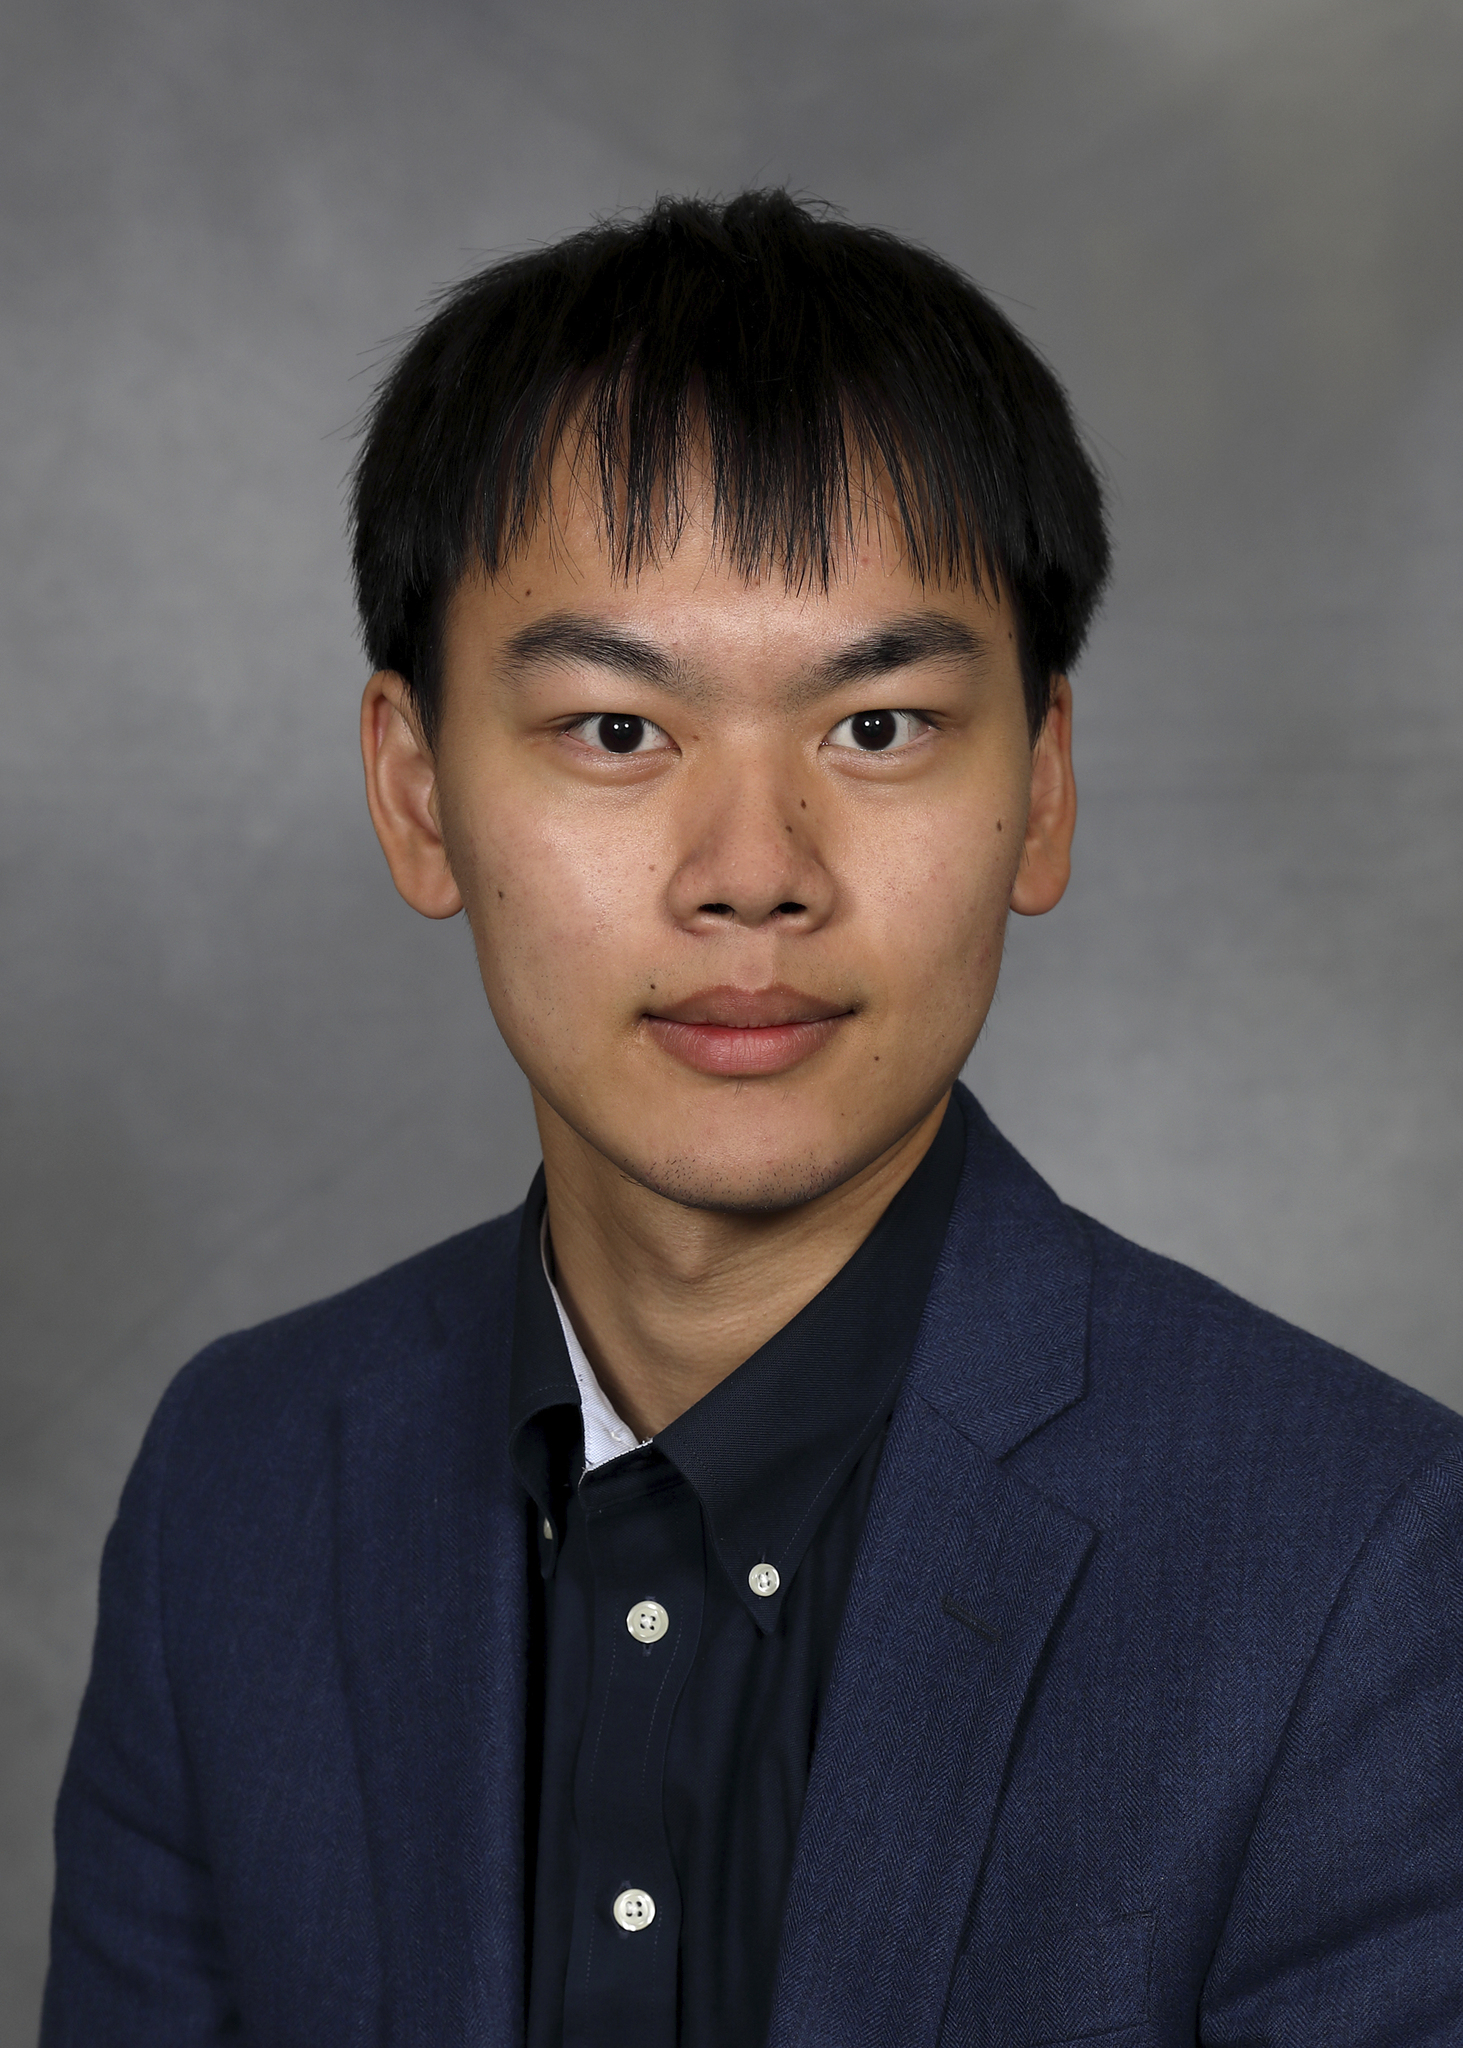
I am Jiamin Xu, a second-year Ph.D. student in Operations Research and Information Engineering (ORIE) at Cornell Tech, where I am fortunate to be advised by Prof. Kyra Gan.
My research focuses on developing reinforcement learning algorithms that are both theoretically grounded and practical for real-world decision-making problems in domains such as healthcare and finance. In particular, I am interested in three fundamental questions: (1) how to identify the right state from high-dimensional raw observations, making reinforcement learning applicable and effective in real-world settings; (2) how to define and learn meaningful reward functions when objectives are implicit; and (3) how to improve the sample efficiency of reinforcement learning under limited interaction budgets.
More broadly, I believe that as the theoretical foundations of reinforcement learning continue to mature and large language models become increasingly capable of modeling complex environments, one of the central challenges is bridging the gap between real-world problems and reinforcement learning formulations. I am also interested in building high-fidelity simulators for domains where collecting real-world interaction data is prohibitively expensive, enabling RL agents to be trained safely and efficiently.
Prior to Cornell, I received my B.S. in Mathematics from Fudan University. During my undergraduate studies, I had the opportunity to work with Prof. David Simchi-Levi on problems in contextual bandits and adaptive experimental design.